
Docker 빌드는 위쪽 레이어부터 캐시를 재사용하므로 자주 바뀌는 지시어를 아래에 두어야 빌드 속도를 유지할 수 있습니다. 영속·공유 데이터는 컨테이너가 삭제될 때 함께 사라지는 overlay 쓰기 레이어가 아니라 volume 또는 bind mount에 보관해야 합니다. 이 글은 Docker 스터디 시리즈의 마지막 4편으로, 공식 빌드 캐시·스토리지 문서를 기준으로 이미지 레이어 캐시를 살리는 Dockerfile 작성법과 컨테이너 삭제 후에도 데이터를 안전하게 보존하는 마운트 전략을 정리합니다.
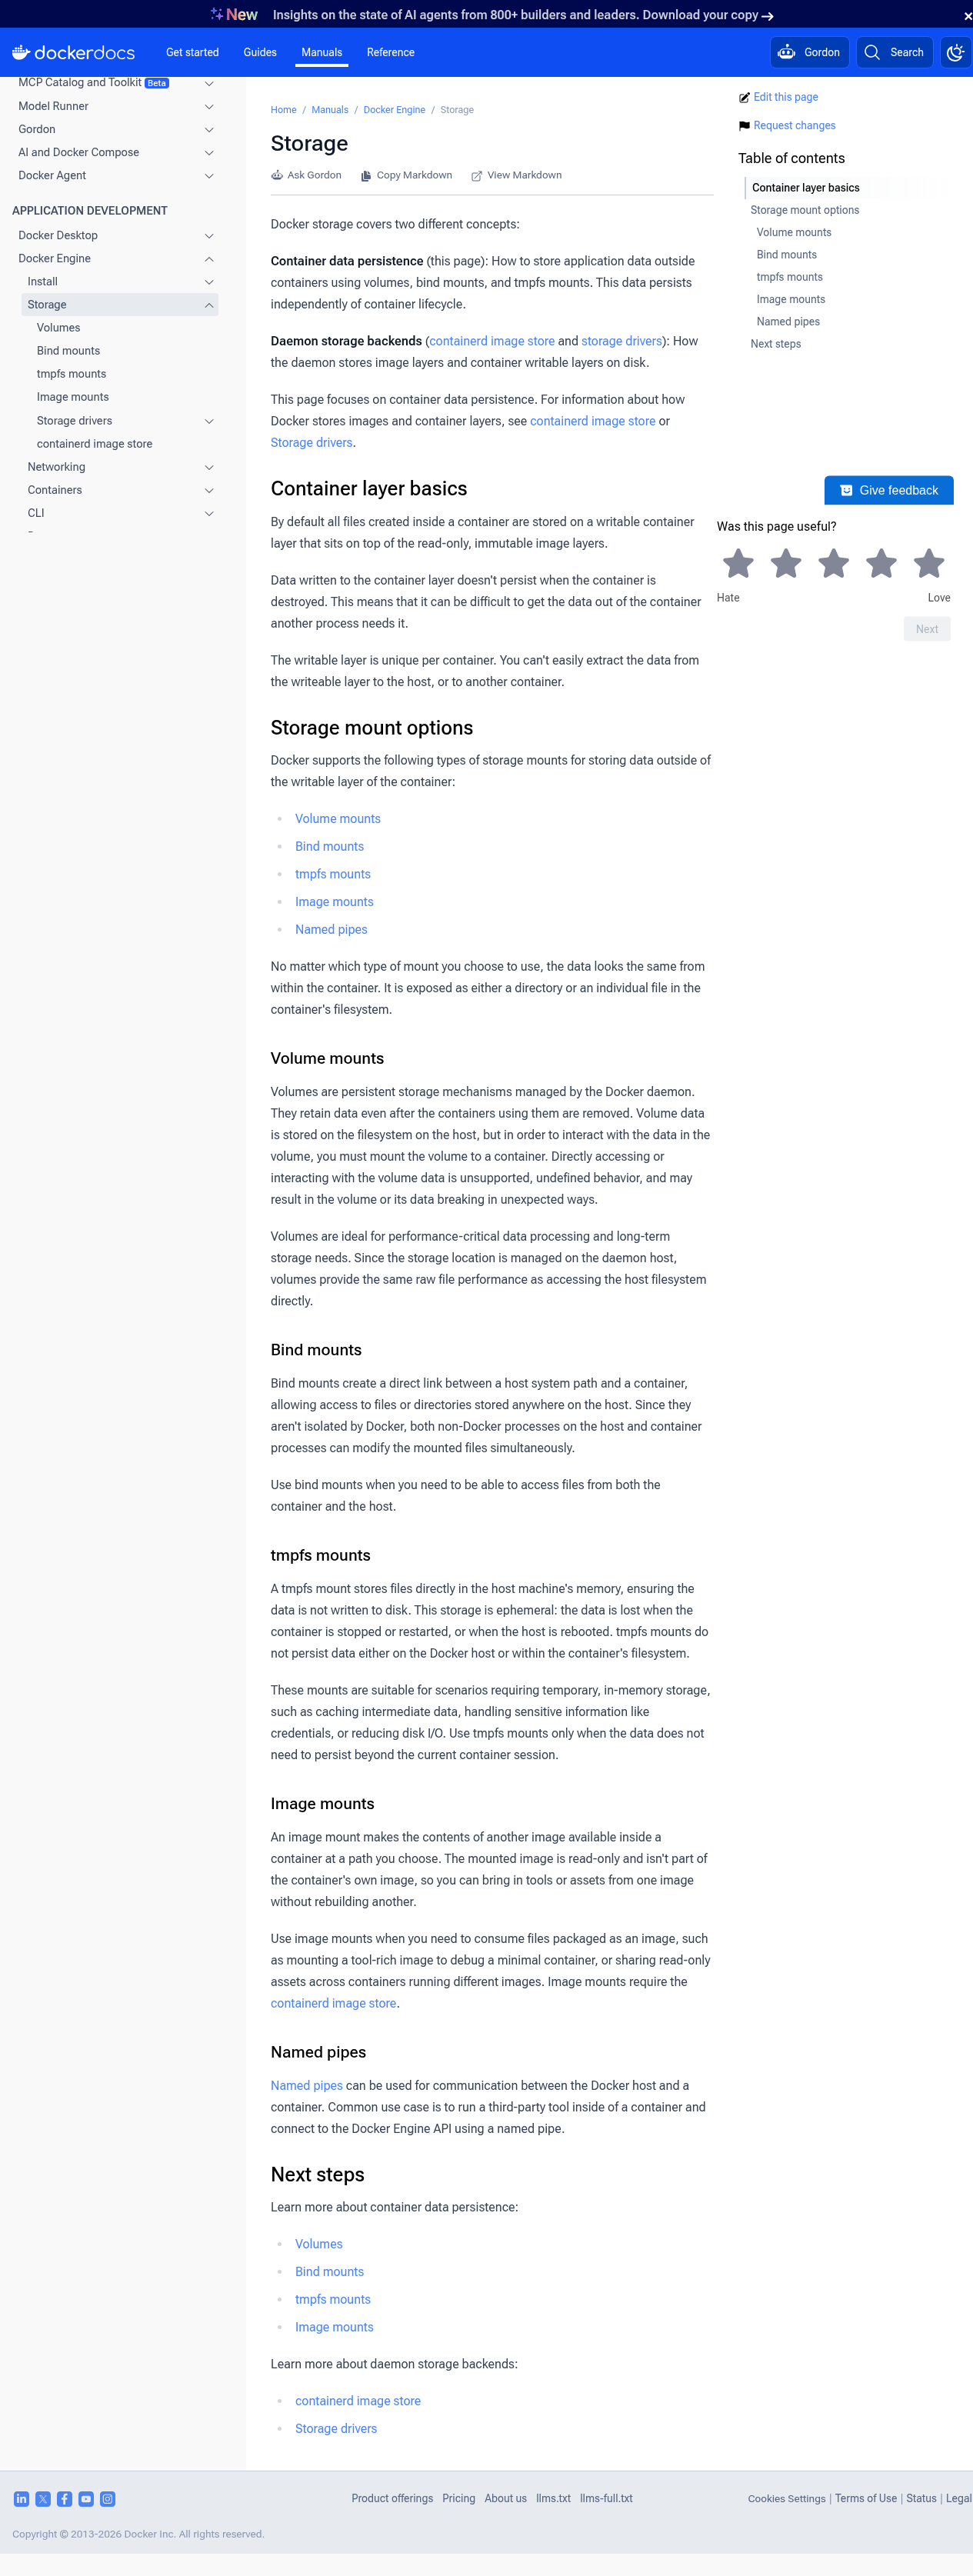
이미지 레이어 캐시는 언제 무효화되나?
한 줄 답: Dockerfile의 한 스텝(레이어)이 변경되면 그 스텝과 이후의 모든 스텝 캐시가 무효화됩니다.
Docker 빌드는 Dockerfile의 각 명령어를 순서대로 실행하며, 각 명령어 결과를 레이어 캐시로 저장합니다. 다음 빌드 시 Docker는 위쪽(앞) 레이어부터 캐시 재사용 여부를 판단합니다. 특정 스텝의 내용이 이전 빌드와 동일하다면 해당 레이어의 캐시가 사용됩니다. 그러나 하나의 스텝이라도 변경되면, 그 스텝 이후의 모든 레이어 캐시는 전부 무효화되어 다시 실행됩니다. 이것이 레이어 캐시 무효화(cache invalidation)의 핵심 규칙입니다.
공식 빌드 캐시 문서에 따르면 다음과 같은 경우에 캐시가 무효화됩니다.
RUN·COPY·ADD등 명령어의 내용 자체가 달라진 경우COPY또는ADD로 복사하는 파일의 내용(체크섬)이 달라진 경우- 부모 레이어(앞 스텝)의 캐시가 무효화된 경우(연쇄 무효화)
따라서 소스 파일이 자주 바뀌더라도, 그 소스를 COPY하는 스텝 위쪽에 자주 변하지 않는 명령어(의존성 설치 등)를 배치하면 캐시 히트율을 높일 수 있습니다.
Docker BuildKit은 병렬 빌드·마운트 캐시 등 고급 캐시 기능을 제공하지만, 본편에서는 필수 스터디 범위인 레이어 캐시 무효화 규칙에 집중합니다. BuildKit의 --mount=type=cache 같은 고급 캐시 마운트는 별도 학습 주제로 남겨 둡니다.
이 캐시 원리는 Docker 볼륨 선택 전략과도 연결됩니다. 빌드 결과물이나 런타임 데이터를 overlay 쓰기 레이어에 두면 캐시 이점이 줄어들 뿐 아니라 컨테이너 삭제 시 데이터도 사라지므로, 다음 섹션에서 다루는 마운트 방식이 중요합니다.
Dockerfile에서 캐시를 살리는 지시어 순서는?
한 줄 답: 자주 변경되지 않는 지시어를 위쪽에, 자주 변경되는 지시어를 아래쪽에 배치합니다. 의존성 설치와 소스 코드 복사를 반드시 분리해야 합니다.
캐시 무효화는 순서대로 전파됩니다. 따라서 자주 바뀌지 않는 것을 먼저, 자주 바뀌는 것을 나중에 두는 것이 기본 원칙입니다. Node.js 프로젝트를 예로 들면 다음과 같습니다.
비효율적인 순서 (캐시 손실):
FROM node:20-alpine
COPY . .
RUN npm install
CMD ["node", "index.js"]
위 구조에서는 소스 파일 한 줄이 바뀔 때마다 COPY . .의 캐시가 무효화되고, 그 결과 RUN npm install도 매번 다시 실행됩니다. 의존성 패키지가 바뀌지 않았어도 전체 설치를 반복하게 됩니다.
효율적인 순서 (캐시 보존):
FROM node:20-alpine
COPY package.json package-lock.json ./
RUN npm install
COPY . .
CMD ["node", "index.js"]
이렇게 하면 package.json과 package-lock.json이 바뀌지 않는 한 RUN npm install 레이어의 캐시가 유지됩니다. 소스 코드가 아무리 자주 바뀌어도 의존성 설치는 건너뜁니다.
이 원칙은 언어와 무관하게 동일하게 적용됩니다.
- Python:
COPY requirements.txt→RUN pip install→COPY . . - Go:
COPY go.mod go.sum→RUN go mod download→COPY . . - Java(Maven):
COPY pom.xml→RUN mvn dependency:resolve→COPY src ./src
핵심은 변경 빈도가 낮은 레이어를 위쪽에 두어, 그 아래 레이어의 캐시 무효화가 발생하지 않도록 보호하는 것입니다.
named volume은 무엇이고 어디에 쓰나?
한 줄 답: named volume은 Docker가 직접 관리하는 영속 스토리지로, 컨테이너 생명주기와 독립적이며 컨테이너 간 공유도 가능합니다.
3편에서 살펴본 대로, 컨테이너의 쓰기 레이어(upperdir)는 컨테이너가 docker rm으로 삭제될 때 영구적으로 함께 사라집니다. 데이터베이스 파일·업로드 파일·애플리케이션 로그처럼 컨테이너 삭제 후에도 남아야 하는 데이터를 쓰기 레이어에 두는 것은 적절하지 않습니다.
Volumes(named volume)는 이 문제를 해결하기 위한 Docker 공식 권장 방식입니다. named volume의 주요 특징은 다음과 같습니다.
- Docker 관리: 볼륨의 생성·저장·삭제는 Docker가 담당하며, 호스트 내 특정 경로(보통
/var/lib/docker/volumes/하위)에 저장됩니다. - 컨테이너와 독립적: 컨테이너를 삭제해도 볼륨 데이터는 남아 있으며, 새 컨테이너에 다시 연결할 수 있습니다.
- 컨테이너 간 공유: 여러 컨테이너가 동일한 볼륨을 마운트하여 데이터를 공유할 수 있습니다.
- write-heavy 워크로드에 적합: overlay 쓰기 레이어와 달리 볼륨은 OverlayFS를 거치지 않고 호스트 파일시스템에 직접 읽고 씁니다. 공식 스토리지 드라이버 문서는 I/O가 많은 워크로드에 볼륨 사용을 권고합니다.
named volume 사용 예시는 다음과 같습니다.
# 볼륨 생성
docker volume create mydata

# 컨테이너에 볼륨 연결 (--mount 방식)
docker run --mount type=volume,source=mydata,target=/app/data myimage

# 볼륨 목록 확인
docker volume ls

# 볼륨 상세 정보
docker volume inspect mydata
source에 지정한 이름(mydata)이 named volume의 이름입니다. 이름을 지정하지 않으면 Docker가 임의의 해시값으로 이름을 생성하는 익명 볼륨(anonymous volume)이 됩니다. 데이터 관리 편의상 이름을 명시하는 named volume이 권장됩니다.

bind mount는 volume과 어떻게 다르고 언제 쓰나?
한 줄 답: bind mount는 호스트의 임의 경로를 컨테이너에 직접 연결하는 방식으로, Docker가 관리하지 않으며 개발 환경에서 소스 코드나 설정 파일을 주입할 때 유용합니다.
Bind mounts는 호스트 파일시스템의 특정 디렉터리 또는 파일을 컨테이너 내 경로에 직접 연결합니다. named volume과 달리 Docker가 스토리지를 생성·관리하지 않으며, 호스트 경로가 미리 존재해야 합니다.
bind mount는 다음 상황에서 주로 활용됩니다.
- 개발 시 소스 코드를 컨테이너 안에서 즉시 반영(hot reload)하고 싶을 때
- 호스트의 설정 파일(
nginx.conf,.env등)을 컨테이너에 주입할 때 - 컨테이너에서 생성한 파일을 호스트 경로에 직접 출력해야 할 때
단, 다음 사항에 주의해야 합니다.
- 이식성: 호스트의 절대 경로에 의존하므로, 다른 개발 환경이나 운영 서버에서 동일한 경로가 보장되지 않으면 동작하지 않을 수 있습니다.
- 권한: 호스트 사용자와 컨테이너 사용자의 UID/GID가 달라 권한 문제가 발생할 수 있습니다.
- 보안: 민감한 호스트 경로를 마운트할 경우 컨테이너가 호스트에 넓게 접근할 수 있어 주의가 필요합니다.
Volume vs Bind Mount 비교
| 항목 | Named Volume | Bind Mount |
|---|---|---|
| 관리 주체 | Docker | 사용자(호스트 파일시스템 직접 관리) |
| 영속성 | 컨테이너 삭제 후에도 데이터를 유지합니다. | 호스트 경로가 유지되는 한 데이터를 유지합니다. |
| 이식성 | 높음 (Docker가 경로를 추상화) | 낮음 (호스트 절대 경로에 의존) |
| 성능 | I/O 직접 접근, write-heavy에 유리 | I/O 직접 접근 (동등 수준) |
| 권장 용도 | DB, 업로드, 로그 등 영속 데이터 | 개발 시 소스 마운트, 설정 파일 주입 |
| 초기화 동작 | 빈 볼륨은 이미지 내용으로 초기화됩니다. | 호스트 경로 내용이 컨테이너 경로를 덮어씁니다. |
--mount와 -v 중 무엇을 권장하나?
한 줄 답: 공식 문서는 타입을 명시적으로 지정할 수 있는 --mount 구문을 권장합니다.
Docker는 마운트를 지정하는 두 가지 플래그를 제공합니다.
-v / --volume (단축 플래그):
# named volume
docker run -v mydata:/app/data myimage

# bind mount
docker run -v /host/path:/container/path myimage
-v는 콜론(:)으로 구분된 축약 문법으로, 콜론 앞에 이름이 오면 named volume, 절대 경로가 오면 bind mount로 해석됩니다. 역사적으로 널리 사용되어 왔으나, 인수의 의미가 위치에 따라 달라져 타입 혼동이 발생할 수 있습니다.
--mount (명시적 플래그):
# named volume
docker run --mount type=volume,source=mydata,target=/app/data myimage

# bind mount
docker run --mount type=bind,source=/host/path,target=/container/path myimage

# tmpfs
docker run --mount type=tmpfs,target=/tmp/secret myimage
--mount는 type=, source=, target= 키-값 쌍으로 마운트 유형과 경로를 명시적으로 지정합니다. 공식 Docker 문서는 --mount의 표현이 더 명확하여 오해를 줄일 수 있다고 안내합니다. 새로운 코드나 문서에서는 --mount를 사용하는 것이 좋습니다.
tmpfs 마운트 간략 소개:
type=tmpfs를 사용하면 컨테이너에 호스트 메모리를 임시 마운트할 수 있습니다. tmpfs의 특징은 다음과 같습니다.
- 데이터가 호스트 메모리에만 존재하며 디스크에 기록되지 않습니다.
- 컨테이너가 중지되면 데이터는 즉시 사라집니다(비영속).
- API 키·세션 토큰처럼 디스크에 남기고 싶지 않은 민감한 임시 파일을 다루는 데 적합합니다.
시리즈 정리: run → load → overlay → cache/mount를 한 줄로 연결하면?
한 줄 답: 격리된 환경을 만들고(1편), 이미지 파일을 이동시키며(2편), 레이어를 합쳐 파일시스템 뷰를 구성하고(3편), 빌드 캐시를 최적화하며 영속 마운트로 데이터를 분리합니다(4편).
이 시리즈는 Docker의 필수 핵심 개념을 4편으로 나누어 살펴보았습니다.
- 1편 — 네임스페이스·cgroups·run: Docker가 리눅스 네임스페이스와 cgroups로 프로세스를 격리하고,
docker run이 이미지로부터 컨테이너를 시작하는 과정을 정리했습니다. - 2편 — docker load·save·export: 이미지 파일을
docker save/docker load로 이동하거나,docker export/docker import로 컨테이너 파일시스템을 추출하는 방법을 다뤘습니다. - 3편 — overlay2 스토리지: OverlayFS의 lowerdir·upperdir·merged 구조로 이미지 레이어가 하나의 파일시스템으로 합쳐지는 메커니즘, copy-on-write, 쓰기 레이어의 임시성을 살펴봤습니다.
- 4편 — 레이어 캐시·볼륨·바인드 마운트 (이 글): 빌드 캐시 무효화 규칙을 활용한 Dockerfile 순서 최적화, named volume과 bind mount의 차이,
--mount구문 활용으로 시리즈를 마무리합니다.
한 줄 맵으로 정리하면: 네임스페이스·cgroups로 격리(1편 run) → tar 아카이브로 이미지 이동(2편 load) → OverlayFS로 레이어 통합(3편 overlay) → Dockerfile 캐시 순서 최적화 및 volume·bind mount로 데이터 영속화(4편 cache/mount).
이것으로 Docker 스터디 미니 시리즈를 마칩니다. 각 편의 개념이 서로 연결되어 있으므로, 앞 편의 개념이 모호하다면 해당 편을 다시 확인하시기 바랍니다.
FAQ
| 질문 | 답변 |
|---|---|
| tmpfs는 언제 사용하나요? | 컨테이너나 호스트 디스크에 저장하고 싶지 않은 민감한 임시 데이터(API 키, 세션 토큰 등)를 처리할 때 적합합니다. 컨테이너가 중지되면 데이터는 즉시 사라지며, 디스크에는 기록되지 않습니다. |
| 볼륨(Volume)은 컨테이너를 삭제하면 어떻게 되나요? | 볼륨은 컨테이너 생명주기와 독립적으로 관리됩니다. docker rm으로 컨테이너를 삭제해도 볼륨 데이터는 유지됩니다. 볼륨을 삭제하려면 docker volume rm을 별도로 실행해야 합니다. |
docker export로 볼륨 데이터도 내보낼 수 있나요? (2편 복습) |
아닙니다. docker export는 컨테이너의 파일시스템 스냅샷(overlay merged 뷰)만 내보냅니다. 마운트된 볼륨이나 bind mount의 데이터는 포함되지 않습니다. 볼륨 데이터를 백업하려면 별도의 방법(임시 컨테이너로 볼륨을 마운트 후 tar로 아카이브 등)을 사용해야 합니다. |
| bind mount 사용 시 주의할 점은? | 호스트의 절대 경로에 직접 의존하므로 다른 환경(CI 서버, 동료 개발 머신 등)에서 동일한 경로가 존재하지 않으면 동작하지 않을 수 있습니다. 이식성이 중요한 프로덕션 데이터 보관에는 named volume을 사용하는 것이 권장됩니다. |
출처
한 줄 답: 본문 사실은 2026-09-14 기준으로 확인한 Docker 공식 빌드 캐시·스토리지 문서를 사용합니다.
- Build cache — Docker Docs — 레이어 캐시 무효화 규칙, BuildKit 캐시 개요를 확인했습니다.
- Manage data in Docker — Docker Docs — volumes·bind mounts·tmpfs 개요 및 비교를 참조했습니다.
- Volumes — Docker Docs — named volume 개념, 사용법, write-heavy 권고를 확인했습니다.
- Bind mounts — Docker Docs — bind mount 동작 방식과 주의사항을 확인했습니다.
- tmpfs mounts — Docker Docs — tmpfs 특성 및 사용 사례를 참조했습니다.
- Storage drivers overview — Docker Docs — 쓰기 레이어 임시성 및 volume 권고 배경을 확인했습니다.
이 글은 Docker 공식 빌드 캐시·스토리지 문서를 기준으로 한 일반 안내이며, BuildKit 설정·엔진 버전·오케스트레이터 환경에 따라 권장 마운트 방식과 캐시 동작은 달라질 수 있습니다.
Docker builds reuse layer cache from the top down, so frequently changing instructions should be placed at the bottom of the Dockerfile to preserve build speed. Persistent or shared data must not be stored in the overlay writable layer — which is permanently destroyed when the container is removed — but instead in a Docker volume or bind mount. This is the fourth and final part of the Docker study series, covering build cache optimization and data persistence strategies based on the official Docker build cache and storage documentation.
When is the image layer cache invalidated?
Short answer: When one build step (layer) changes, the cache for that step and all subsequent steps is invalidated.
Docker builds execute each Dockerfile instruction in sequence and stores the result of each instruction as a cached layer. On the next build, Docker checks from the topmost layer downward to determine whether each layer can be reused. If a step's content is identical to the previous build, its cached layer is used. However, if any one step changes, the caches for all subsequent layers are invalidated and those steps are re-executed. This cascading behavior is the core rule of build cache invalidation.
According to the official Docker build cache documentation, cache is invalidated in the following cases.
- The content of the instruction itself changes (e.g., a different
RUNcommand or different arguments toCOPY). - For
COPYandADDinstructions, the checksum of the files being copied has changed. - A parent layer (an earlier step) had its cache invalidated, triggering cascading invalidation of all later steps.
Even if source files change frequently, placing infrequently changing instructions — such as dependency installation — above the source copy step keeps the cache hit rate high for those early layers.
Docker BuildKit provides advanced caching features such as parallel builds and cache mounts, but this article focuses on the essential cache invalidation rules relevant to this study series. Advanced features like --mount=type=cache are topics for further exploration beyond the scope of these fundamentals.
What is the optimal instruction order in a Dockerfile to preserve cache?
Short answer: Place infrequently changing instructions at the top and frequently changing instructions at the bottom. Always separate dependency installation from source code copying.
Because cache invalidation propagates downward, the guiding principle is: put what changes rarely first; put what changes often last. Using a Node.js project as an example:
Inefficient order (cache loss):
FROM node:20-alpine
COPY . .
RUN npm install
CMD ["node", "index.js"]
In this structure, any change to a source file invalidates the COPY . . layer, causing RUN npm install to re-execute every time — even when no dependency has changed.
Efficient order (cache preserved):
FROM node:20-alpine
COPY package.json package-lock.json ./
RUN npm install
COPY . .
CMD ["node", "index.js"]
With this structure, the RUN npm install layer cache is preserved as long as package.json and package-lock.json remain unchanged, regardless of how often source files are modified.
The same principle applies regardless of language or runtime.
- Python:
COPY requirements.txt→RUN pip install→COPY . . - Go:
COPY go.mod go.sum→RUN go mod download→COPY . . - Java (Maven):
COPY pom.xml→RUN mvn dependency:resolve→COPY src ./src
The goal is to place lower-churn layers near the top so that higher-churn layers below them can be invalidated without cascading back up to the expensive dependency installation step.
What is a named volume and where should it be used?
Short answer: A named volume is Docker-managed persistent storage that is independent of any container's lifecycle and can be shared between containers.
As established in part 3, the container's writable layer (upperdir) is permanently destroyed when the container is removed with docker rm. Placing data that must outlive a container — such as database files, uploaded files, or application logs — in that writable layer is therefore inappropriate.
Named volumes are a type of Docker volume officially recommended for persistent container data. Their key characteristics are as follows.
- Docker-managed: Docker handles volume creation, storage location (typically under
/var/lib/docker/volumes/), and lifecycle. Users interact with volumes by name, not by host path. - Independent of containers: Removing a container does not delete its associated volume. The volume persists and can be attached to a new container.
- Shareable: Multiple containers can mount the same named volume simultaneously, enabling data sharing between them.
- Preferred for write-heavy workloads: Unlike the overlay writable layer, volumes bypass the OverlayFS stack and read/write directly to the host filesystem. The official Docker storage documentation recommends volumes for I/O-intensive workloads for this reason.
Example usage of a named volume:
# Create a volume
docker volume create mydata

# Attach the volume to a container (using --mount)
docker run --mount type=volume,source=mydata,target=/app/data myimage

# List volumes
docker volume ls

# Inspect volume details
docker volume inspect mydata
The name given to source= is the volume name. Omitting a name creates an anonymous volume identified by a random hash. Named volumes are preferred because they are easier to manage, reference, and reuse.
How does a bind mount differ from a volume, and when should it be used?
Short answer: A bind mount connects an arbitrary host path directly into the container and is not managed by Docker. It is useful for mounting source code or configuration files during development.
Bind mounts map a specific directory or file on the host filesystem to a path inside the container. Unlike named volumes, Docker does not create or manage the storage; the host path must already exist.
Bind mounts are commonly used in the following scenarios.
- Mounting source code into a container during development so that changes are immediately reflected (hot reload) without rebuilding the image.
- Injecting host configuration files (such as
nginx.confor.env) into a container at startup. - Directing output files generated inside the container to a specific location on the host.
However, be aware of the following caveats.
- Portability: Bind mounts depend on an absolute host path. If the same path does not exist on another machine or environment, the mount will fail or behave unexpectedly.
- Permissions: Mismatched UID/GID between the host user and the container user can cause permission errors.
- Security: Mounting sensitive host directories gives the container broad access to those paths, which requires careful consideration.
Volume vs Bind Mount Comparison
| Aspect | Named Volume | Bind Mount |
|---|---|---|
| Managed by | Docker | User (host filesystem managed directly) |
| Persistence | Data survives container removal | Data persists as long as the host path exists |
| Portability | High (Docker abstracts the path) | Low (depends on a specific host absolute path) |
| Performance | Direct host I/O; well-suited for write-heavy use | Direct host I/O (comparable) |
| Best use | Databases, uploads, logs, persistent app data | Dev source mounts, config file injection |
| Initialization | Empty volume can be pre-populated from image content | Host path content overwrites the container path |
Should you use --mount or -v?
Short answer: The official Docker documentation recommends --mount for its explicit and unambiguous syntax.
Docker provides two flags for specifying mounts when running a container.
-v / --volume (shorthand flag):
# Named volume
docker run -v mydata:/app/data myimage

# Bind mount
docker run -v /host/path:/container/path myimage
-v uses a colon-separated shorthand. If the left side is a name, Docker treats it as a named volume; if it is an absolute path, it becomes a bind mount. This positional ambiguity can cause confusion about which type of mount is in effect.
--mount (explicit flag):
# Named volume
docker run --mount type=volume,source=mydata,target=/app/data myimage

# Bind mount
docker run --mount type=bind,source=/host/path,target=/container/path myimage

# tmpfs
docker run --mount type=tmpfs,target=/tmp/secret myimage
--mount uses explicit key-value pairs. The type= field makes the intent immediately clear, reducing the chance of misconfiguration. The official Docker documentation states a preference for --mount due to its verbosity and clarity. New scripts and documentation should prefer --mount.
Brief overview of tmpfs mounts:
Using type=tmpfs mounts host memory as a temporary filesystem inside the container. Key characteristics:
- Data exists only in host RAM and is never written to disk.
- Data is lost immediately when the container stops (non-persistent).
- Appropriate for sensitive temporary data — such as API keys or session tokens — that should not be written to any persistent storage.
Series summary: how do run → load → overlay → cache/mount connect in one line?
Short answer: Create isolated environments (part 1), move image files (part 2), merge layers into a filesystem view (part 3), optimize build cache order and separate data with persistent mounts (part 4).
This four-part Docker study series has covered the fundamental concepts that every developer working with Docker needs to understand.
- Part 1 — namespaces, cgroups, and run: How Docker uses Linux namespaces and cgroups to isolate container processes, and how
docker runstarts a container from an image. - Part 2 — docker load, save, and export: How to transfer images between environments using
docker saveanddocker load, and howdocker exportextracts a container filesystem snapshot (without volume data). - Part 3 — overlay2 storage: How OverlayFS combines read-only image layers (lowerdir) with a writable container layer (upperdir) into a merged filesystem view, how copy-on-write works, and why the writable layer is ephemeral.
- Part 4 — layer cache, volumes, and bind mounts (this article): How cache invalidation rules shape Dockerfile instruction order, how named volumes provide Docker-managed persistence independent of the container lifecycle, and how to choose between
--mount type=volume,type=bind, andtype=tmpfs.
The one-line series map: Isolate with namespaces and cgroups (part 1 run) → transfer images as tar archives (part 2 load) → unify layers with OverlayFS (part 3 overlay) → optimize Dockerfile cache order and persist data with volumes and bind mounts (part 4 cache/mount).
This concludes the Docker study mini-series. The concepts across all four parts are interconnected; if any earlier topic feels unclear, revisiting the relevant part is recommended before moving on.
FAQ
| Question | Answer |
|---|---|
| When should I use tmpfs? | Use tmpfs when you need to handle sensitive temporary data — such as API keys or session tokens — that should not be written to the container filesystem or the host disk. The data exists only in host memory and disappears immediately when the container stops. |
| Does a volume survive container removal? | Yes. Volumes are managed independently of the container lifecycle. Removing a container with docker rm does not delete its associated volume. The volume must be explicitly removed with docker volume rm. |
Does docker export include volume data? (Part 2 review) |
No. docker export captures only the container's filesystem snapshot (the overlay merged view at that moment). Data stored in mounted volumes or bind mounts is not included in the exported archive. To back up volume data, use a separate approach such as mounting the volume into a temporary container and archiving its contents with tar. |
| What should I watch out for with bind mounts? | Bind mounts depend on an absolute host path, which may not exist or may differ on other machines (CI servers, teammate environments, production hosts). For data that needs to be reliably portable, use a named volume instead of a bind mount. |
References
Short answer: Facts in this article are drawn from Docker's official build cache and storage documentation checked on 2026-09-14.
- Build cache — Docker Docs — Used to verify layer cache invalidation rules and BuildKit cache overview.
- Manage data in Docker — Docker Docs — Used to verify the storage overview distinguishing volumes, bind mounts, and tmpfs.
- Volumes — Docker Docs — Used to verify named volume concepts, usage, and the write-heavy workload recommendation.
- Bind mounts — Docker Docs — Used to verify bind mount behavior and portability caveats.
- tmpfs mounts — Docker Docs — Used to verify tmpfs characteristics and use cases.
- Storage drivers overview — Docker Docs — Used to verify the ephemeral nature of the writable layer and the volume recommendation background.
This article is a general overview based on Docker's official build cache and storage documentation. Recommended mount strategies and cache behaviors may vary depending on BuildKit configuration, Docker Engine version, and orchestrator environment.
'기타' 카테고리의 다른 글
| Gamsgo 할인·사용법, Cursor·Claude Code 예시 (0) | 2026.09.17 |
|---|---|
| systemd Type= 정리|simple·exec·notify와 서비스 파일 핵심 키워드 (0) | 2026.09.17 |
| GoingBus 할인 받는 법, 가입·쿠폰·주의점 (0) | 2026.09.17 |
| Docker overlay2 스토리지|이미지 레이어가 합쳐지는 방식 (0) | 2026.09.16 |
| docker load·save·run으로 보는 이미지 로드와 실행 (0) | 2026.09.16 |